M
Mark Bridges
Guest
- Thread Author
- #1
AI answer engines now sit on top of all of them. When a buyer asks ChatGPT, Perplexity, Google’s AI answers, Claude, or Grok “which consulting firm should we hire for an SAP implementation,” the AI does the research and hands back a synthesized recommendation in one response. The customer journey that once spread across up to 10 touchpoints has collapsed into what we might call the customer journey singularity: a single answer that stands in for the consideration set, the evaluation, the price check, and the trust assessment all at once.
AI visibility is the measure of whether and how these engines surface, recommend, and represent your brand. It is now a board-level concern, and for most companies it is also a blind spot. AI answers are personalized and ephemeral, and none of it appears in your analytics. A buyer who asks ChatGPT about your category and gets steered to a competitor leaves no trace in your funnel.
Introducing the AI Visibility ANSWER Framework
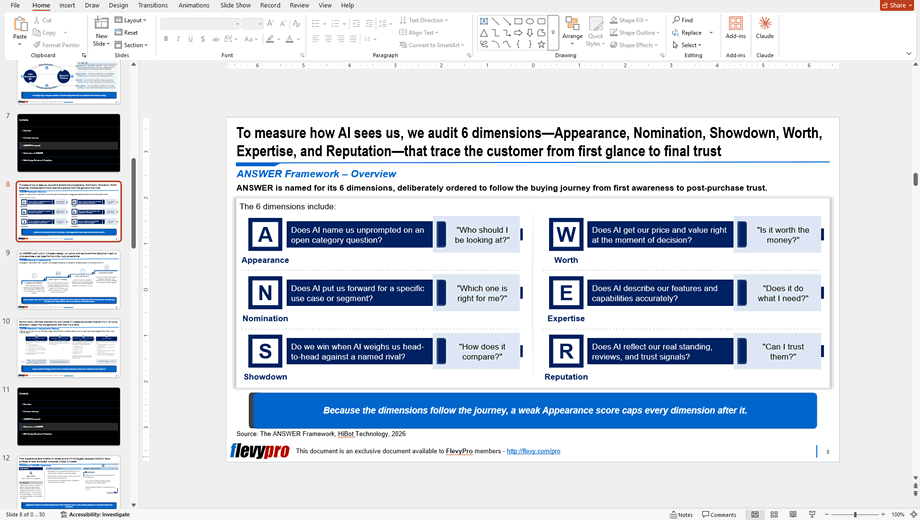
The AI Visibility ANSWER framework, developed by HiBot, breaks AI visibility into 6 measurable categories: Appearance, Nomination, Showdown, Worth, Expertise, and Reputation. The acronym is ordered on purpose. Read A through R and you trace a buyer’s path from first awareness to post-purchase trust. Appearance governs entry into the consideration set. Nomination, Showdown, and Expertise cover active evaluation. Worth sits at the moment of purchase. Reputation closes the loyalty loop.
The mapping to McKinsey’s journey is what makes the framework a diagnosis rather than a checklist: a low score in any category tells you exactly where a brand is leaking out of the buyer’s journey.
Deep Dive: Showdown
Showdown answers the buyer question “how does it stack up against the alternatives?” Buyers no longer build their own comparison matrices. They ask AI to choose: “Accenture vs Deloitte for digital transformation” or “how does your platform compare to a named competitor for warehouse automation?” Showdown measures whether a brand survives that head-to-head or gets dismissed before its strengths are weighed. Deals are won and lost here, because the AI’s verdict often becomes the shortlist.
Deep Dive: Worth
Worth answers “is it worth the money?” and sits at the most dangerous point in the journey: the moment of purchase. Buyers ask AI about cost, value for money, and ROI before they commit. An engine that states the wrong price or frames the brand as overpriced suppresses purchase intent at the exact moment it matters most. A brand can win every earlier phase and still lose here.
Case Study: Accenture
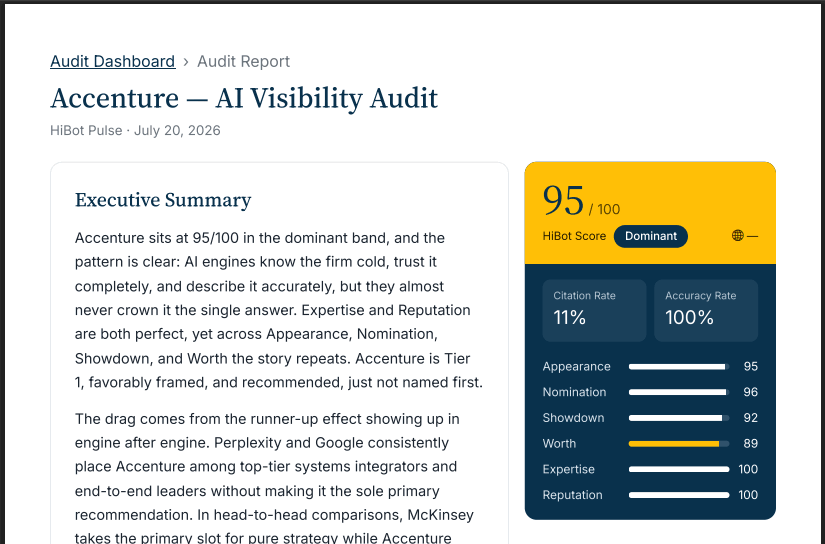
A July 2026 HiBot Pulse audit of Accenture shows why even elite brands need this diagnosis. Accenture scored 95/100, in the dominant band. Expertise and Reputation were both perfect at 100. AI engines describe the firm’s capabilities accurately and reflect its credibility in full. Accuracy across all answers: 100%.
Yet the citation rate was only 11%, and the pattern behind it is what the audit calls the runner-up effect. In Showdown (92), McKinsey takes the primary slot for pure strategy while engines route Accenture to the strategy-plus-implementation lane, and TCS gets held up as an equal counterpoint on cost and scale. In Worth (89, the weakest category), Perplexity and Google cite Accenture’s own ROI research favorably but stop short of recommending the firm, while ChatGPT treats it as a neutral example. Accenture is trusted and accurately described. It is just rarely named first.
The prescription follows: own specific comparison lanes so competitors stop splitting the primary slot, and seed verifiable ROI evidence so engines convert favorable framing into an actual recommendation.
You Cannot Manage What You Cannot See
If a 95/100 brand is leaking at the decision point, consider what an unaudited brand looks like inside the singularity. The first step is measurement, not optimization: a neutral, multi-engine baseline of what AI actually says about you, captured the way a real buyer would see it. That is what a HiBot audit delivers. Get your baseline at hibot.com before your buyers get theirs from ChatGPT.
Interested in learning more about how conduct an AI Visibility Audit using the ANSWER framework? You can download editable PowerPoint presentations on the ANSWER framework and the AI Visibility Audit Process on the Flevy documents marketplace.
Do You Find Value in This Framework?
You can download in-depth presentations on this and hundreds of similar business frameworks from the FlevyPro Library. FlevyPro is trusted and utilized by 1000s of management consultants and corporate executives.
For even more best practices available on Flevy, have a look at our top 100 lists:
- Top 100 in Strategy & Transformation
- Top 100 in Organization & Change
- Top 100 Consulting Frameworks
- Top 100 in Digital Transformation
- Top 100 in Operational Excellence
Last edited: